Web Scraping vs Official API: Which Should You Use?
Before you commission a scraper, check whether an API gives you the same data. Here is how to compare reliability, cost, legality and maintenance, and when scraping is still the right call.
Collecting and processing data reliably: resilient scrapers, government and open-data sources, ETL pipelines and keeping data feeds healthy.
Showing 6 of 6 articles
Before you commission a scraper, check whether an API gives you the same data. Here is how to compare reliability, cost, legality and maintenance, and when scraping is still the right call.
What a custom web scraper costs depends on the target sites, the volume, the anti-bot defences and how reliable it has to be. Here is how to scope it and what to budget for upkeep.

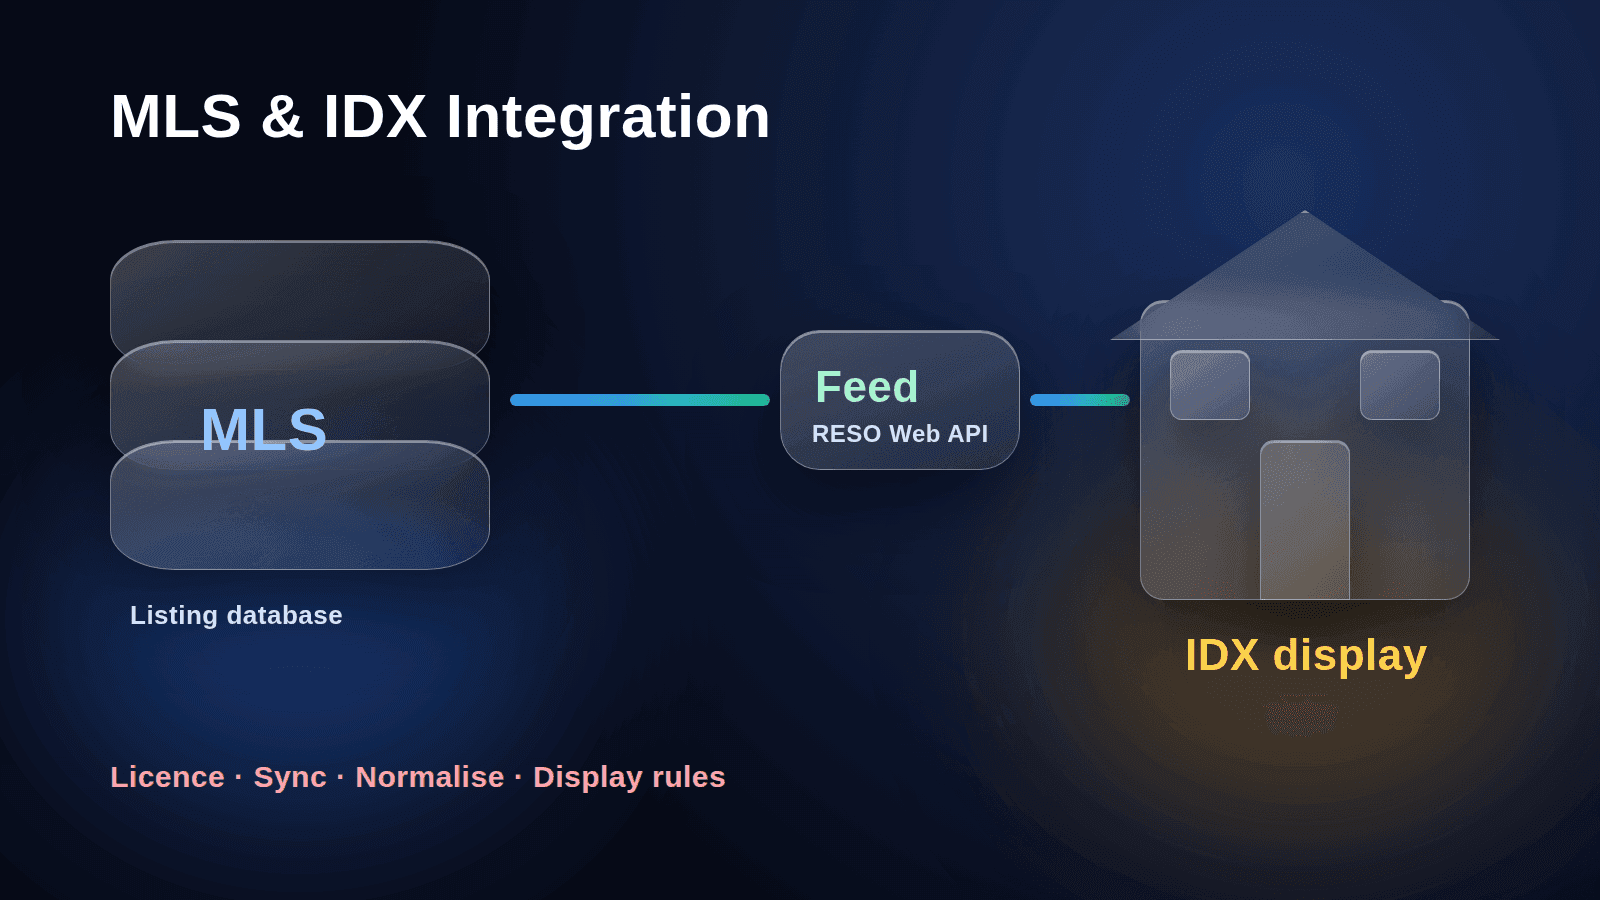
MLS and IDX integration explained: how listing data feeds work, what licensing you need, the architecture to use and the pitfalls to plan for before you build.

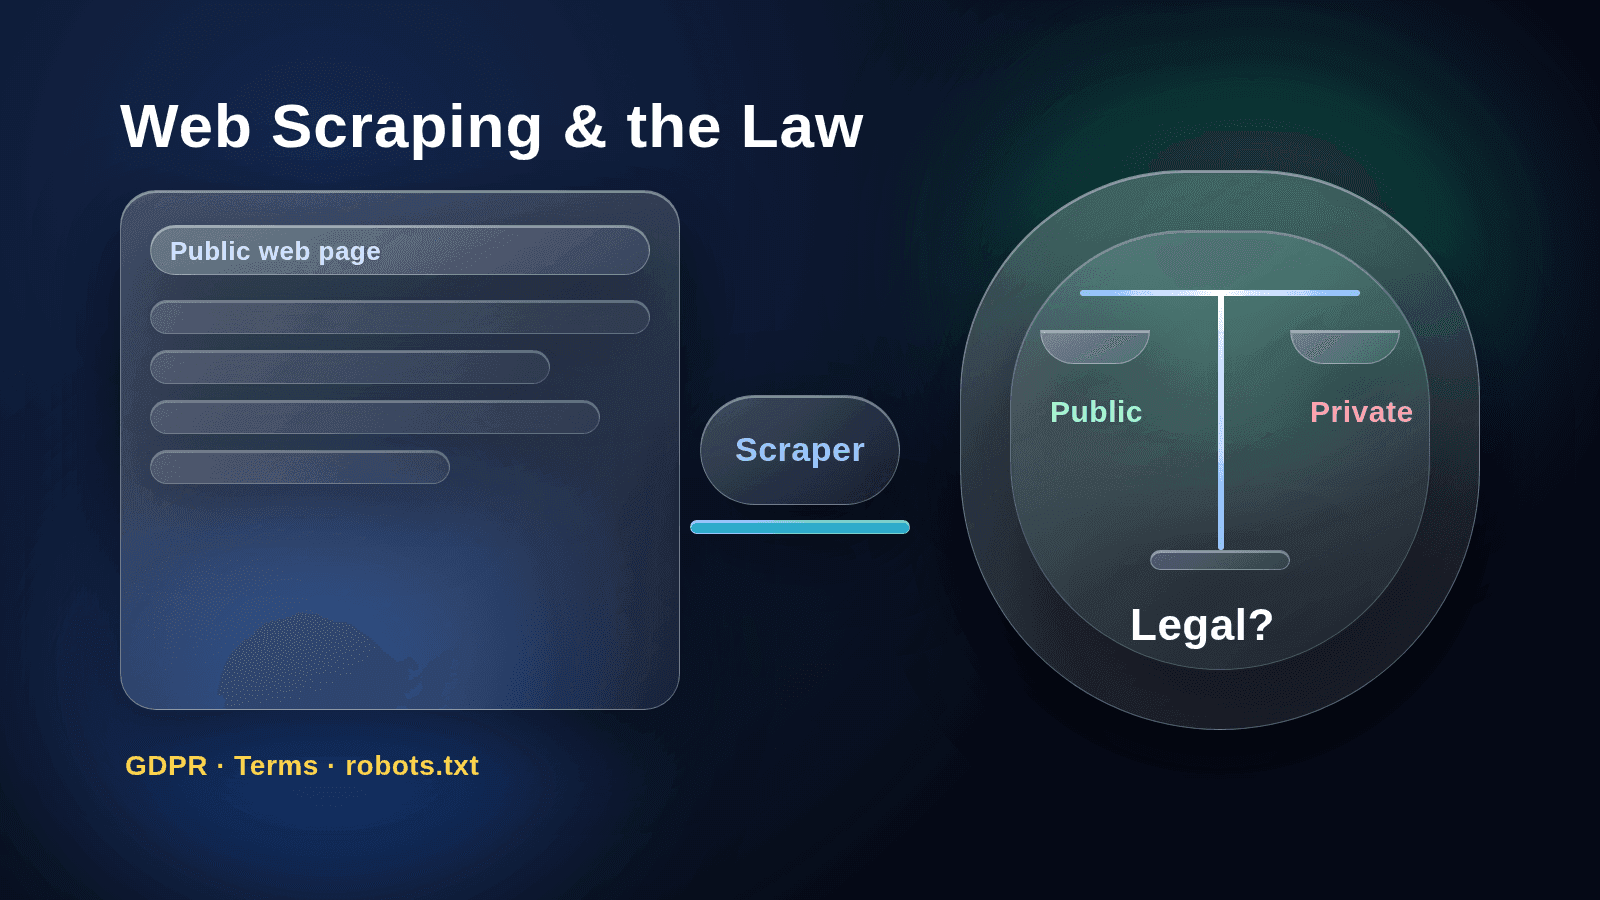
Is web scraping legal for business? Learn when scraping is lower or higher risk, how terms of service, personal data, copyright and robots.txt matter, and a checklist to use first.

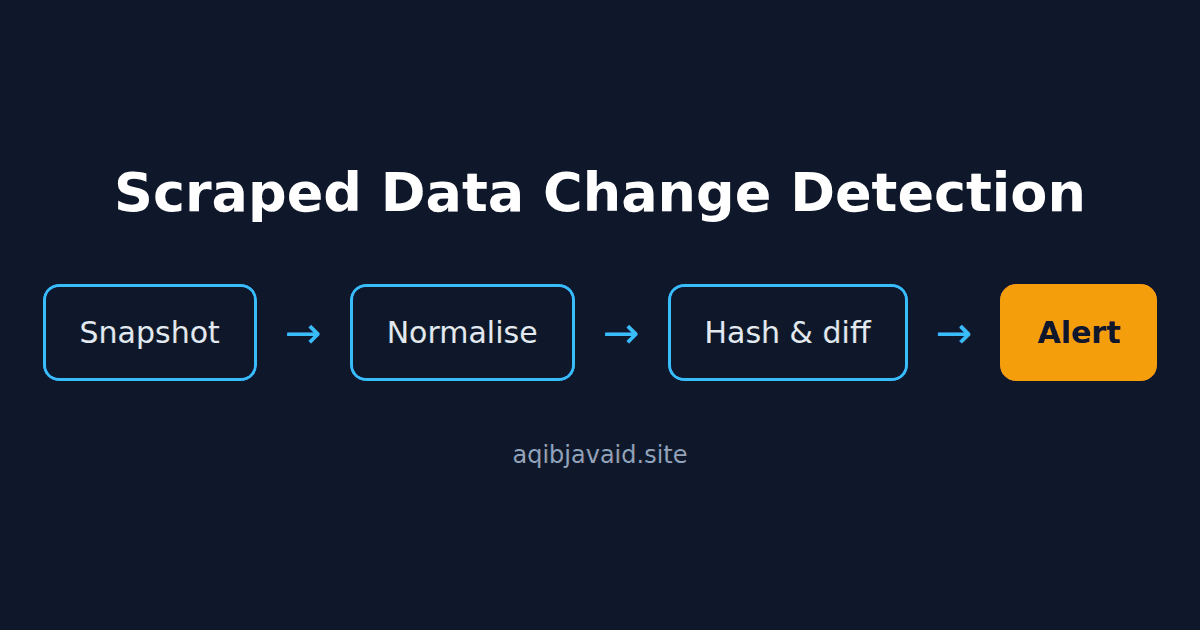
How I design change detection for scraped data: stable record identity, normalisation, content hashing, field-level diffs and alerts users trust, with Laravel and MySQL examples.

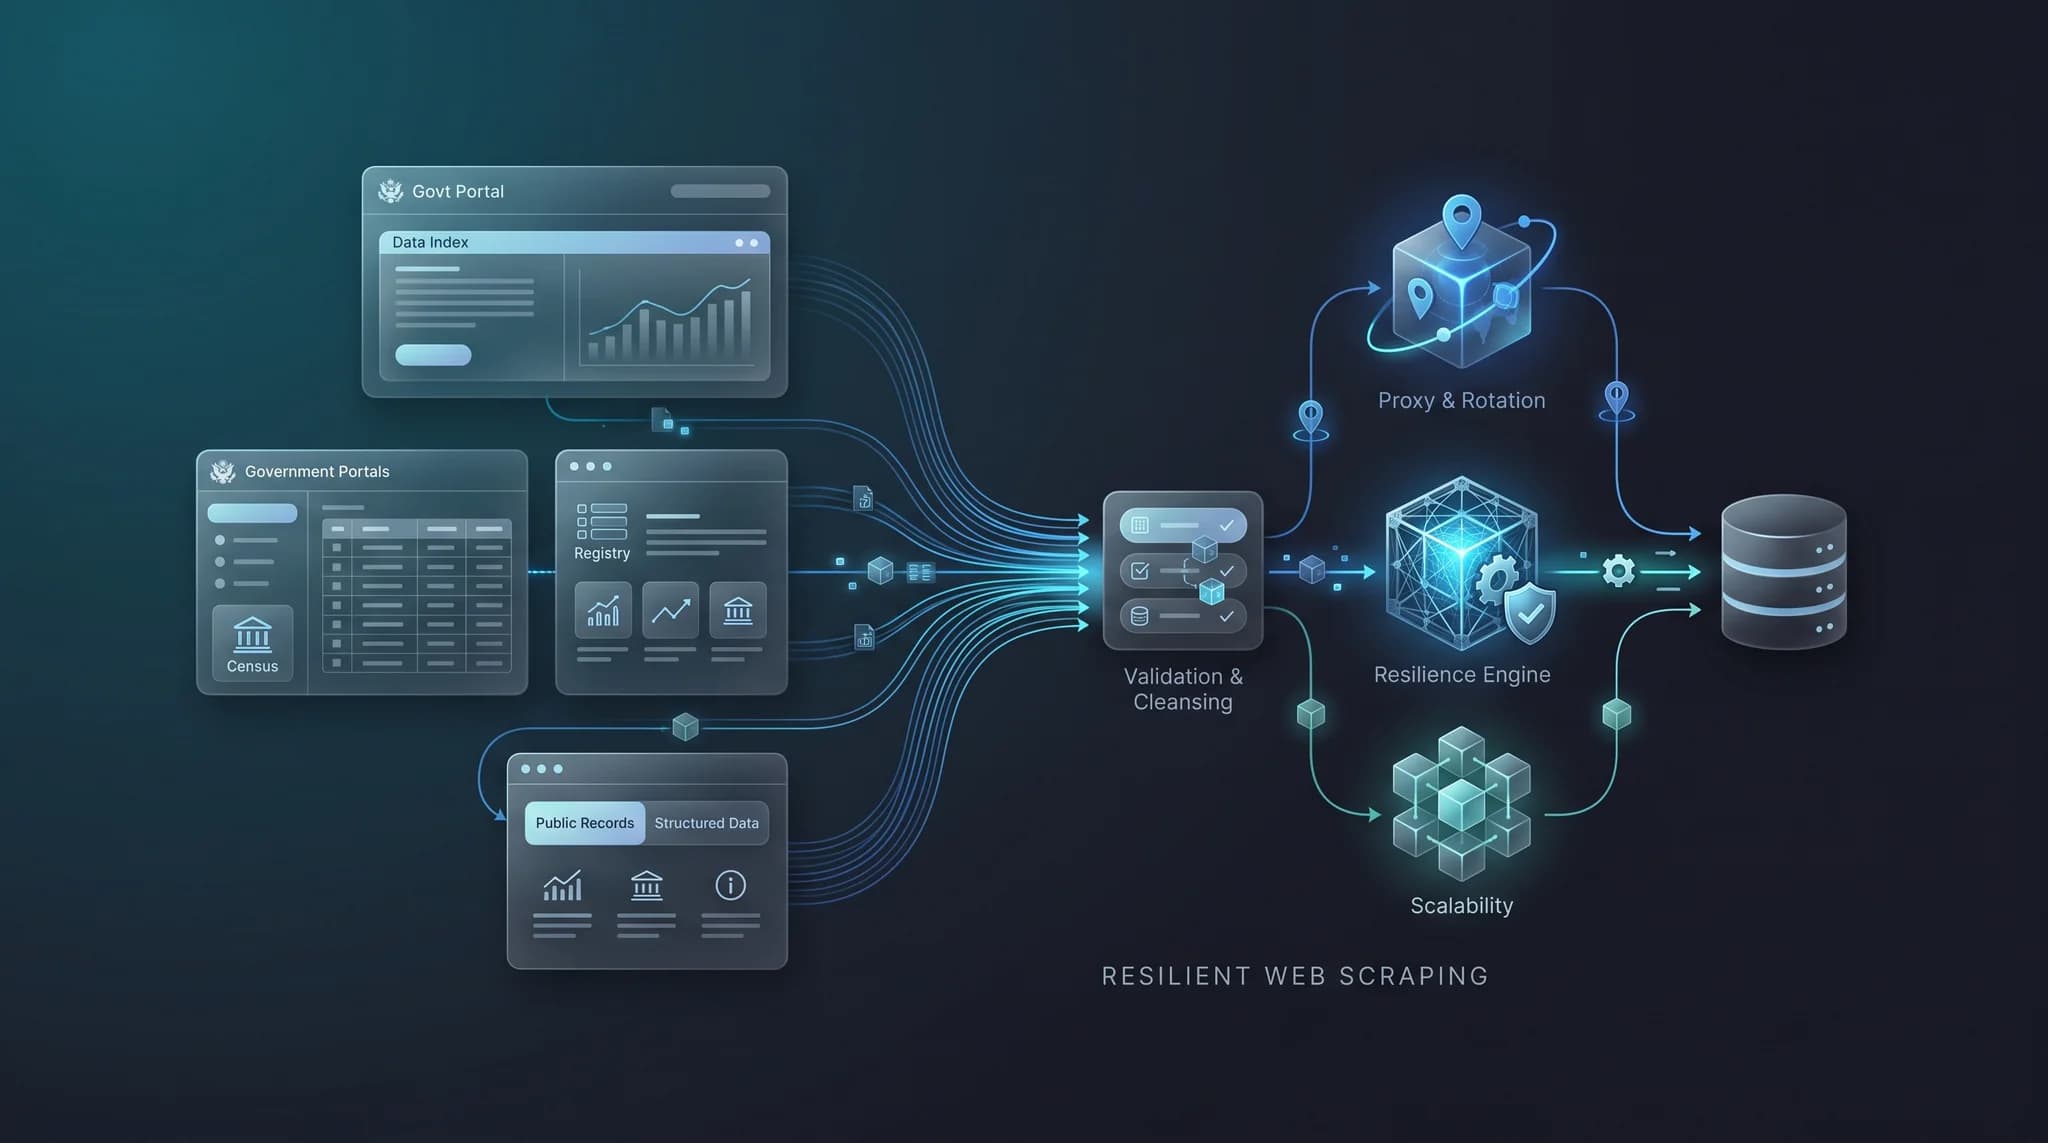
General principles for building web data collection systems that keep working as external sources change: isolation, normalization, failure handling and monitoring.
Pulling data from a page once is easy. Running a pipeline every day for a year, through layout changes, rate limits and outages, without loading garbage into your database is a different job. These articles cover building data collection that lasts, from government and open-data sources to validation, ETL and monitoring.
Need data collected reliably? See web scraping & data extraction and real estate & data platform development, or book a free call.